What LLM training data actually is
LLMs like ChatGPT, Claude or Gemini get their fitness knowledge from text. That is an important difference from a coach who has tried plans out in practice.
During pre-training, the model reads huge amounts of text and learns patterns in it: what follows what, which concepts belong together, how texts are structured. Fitness knowledge comes from reading texts about training, without any training experience of its own.
So the LLM has read thousands of articles on progressive overload, hundreds of studies on periodisation and dozens of books on strength training. From that it has built a picture of "training" without ever touching a barbell. The model knows what is in texts. What is in no text, it does not know.
The model doesn't learn during the conversation
While you chat with ChatGPT, the model doesn't learn anything new. If you correct a bad answer today, it won't automatically know better tomorrow. There are two caveats, though: depending on your settings, your chats can feed into the training of later model versions, and memory features remember things about you. The date up to which the knowledge goes is called the knowledge cutoff. It is like a book's publication date: whatever happened afterwards is not in it.
Where the fitness knowledge comes from
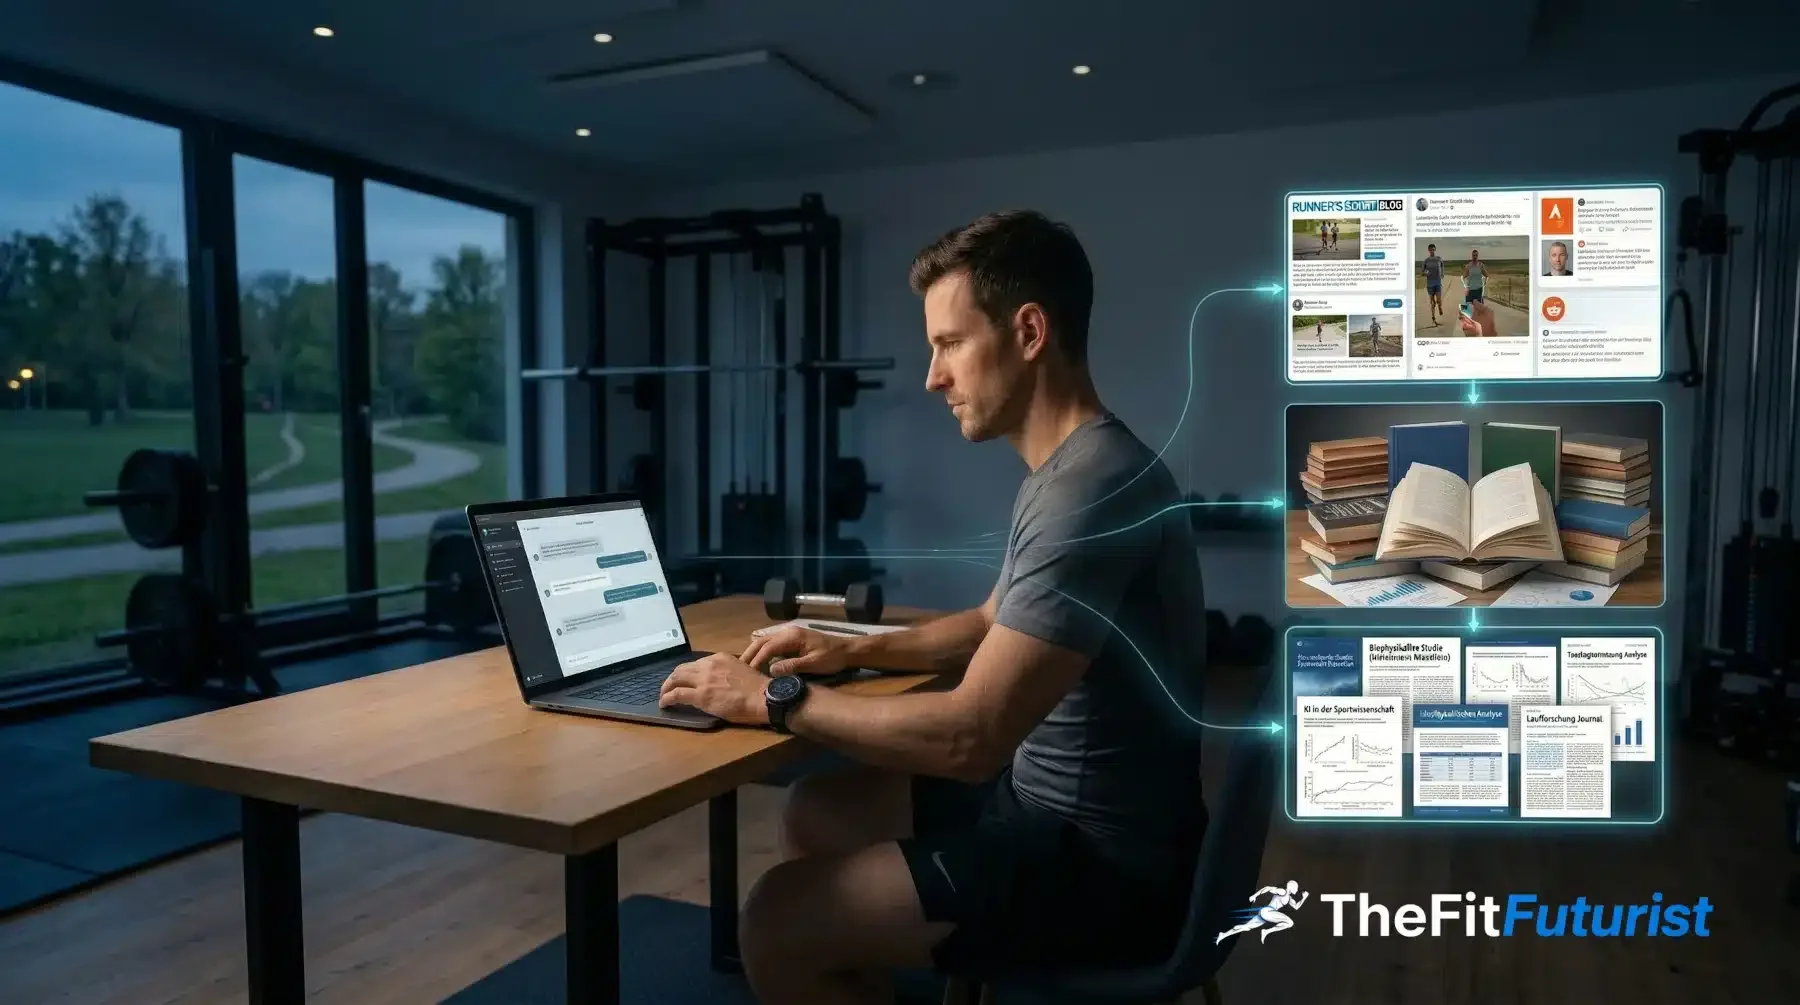
The three main sources of an LLM's training knowledge are websites and blogs, scientific studies and books. Each has its own strengths and its own biases.
Websites and blogs
Websites and blogs make up the largest share of the training data by volume. How large exactly depends on the dataset, usually well over half. The best-known dataset is Common Crawl: an automated collection of billions of web pages that is updated regularly. Fitness blogs, forums and advice sites all end up in it. So an LLM knows topics that are widely discussed online well. Niche methods or new sport-science approaches, hardly at all.
The real problem is the structure behind it. I know this industry and how content often gets made in it. Whether someone uses AI as a writing tool is secondary. It gets tricky when people write about topics they don't master. Training articles then get made by looking at what competitors write and lightly rephrasing it. The result: hundreds of articles with the same core message that confirm each other, whether it is correct or not.
To an LLM, that looks like agreement. The model can't tell whether a text comes from someone with 15 years of coaching experience or from someone who googled for three hours. All it sees is: this claim shows up on many, often well-linked pages. But popular doesn't mean correct, and an LLM can't reliably make that distinction during training.
Scientific studies
Scientific texts from sources like PubMed, arXiv or other academic databases make up a much smaller share depending on the dataset, roughly between 2 and 25%. Sport science is only a small fraction of that. My back-of-the-envelope estimate: it is probably below one percent of the total dataset, there is no exact figure. That is simply down to volume, since medicine, physics and computer science publish many times more.
On top of that there is a bias that runs through the whole literature: for a long time, sport-science research was done mainly on young, male test subjects. An analysis by Cowley et al. (2021) found only 34% female participants in sport-science studies, and only 6% of studies looked exclusively at women. Women, people over 50 and beginners without training experience are therefore underrepresented. That is less about bad intent by researchers than about classic performance-sport research having focused on other groups.
On top of that, not all studies are freely accessible. Articles behind paywalls are probably less well represented in the training data than open-access ones. So what a model knows about sport science also depends on which studies were freely available online, and open access is not yet the norm in sport science.
Books and specialist literature
Books are often the most reliable source, provided they were digitised and made it into the training data. Classics like "Science and Practice of Strength Training" (Zatsiorsky & Kraemer) or "Periodization" (Bompa & Haff) have probably found their way into the training data of major LLMs, though I can't prove it. Their influence on strength-training topics is likely noticeable.
The downside: books have a publication date. Older standard works may contain concepts that newer research has overturned. The LLM doesn't notice; it weighs texts by pattern, not by how current they are.
Source | Share (rough range)* | Strength | Weakness |
|---|
Websites / blogs (Common Crawl) | roughly 30 to over 80% | Broad topic coverage, current discussions | Quality uncontrolled, copy cascades, training myths often rank just as well as serious sources |
Scientific studies (PubMed, arXiv) | roughly 2 to just over 25% | Methodically structured, peer-reviewed | Skewed towards young and male, paywalls, sport science probably under 1% of the total |
Books / specialist literature | under 1 to about 15% | Highest quality, structured knowledge | Only digitised works, potentially outdated, newer revisions missing |
* Rough ranges from publicly documented training datasets such as The Pile, Dolma or C4 and from figures on early LLaMA models. The shares vary a lot between datasets, and the major providers do not disclose their mix.
In short: websites and blogs provide the biggest volume, but with varying quality, copy cascades and myths that rank well. Studies are methodologically cleaner but skewed towards young men and limited by paywalls. Books are the most reliable but often older. And everything after the knowledge cutoff is missing, unless you provide it yourself as context.
Which model knows what: the comparison (as of October 2026)
Not all LLMs have the same sources, and that matters for fitness questions. Knowledge cutoff, data basis and web search all shape what answer quality you can realistically expect.
Snapshot: October 2026
Model versions and knowledge cutoffs change fast. The table shows the state as of October 2026. By the time you read this, it may already be outdated. You can find the current state directly at the provider: OpenAI, Anthropic, Google. The principles behind it, meaning source distribution, gaps in the data and the knowledge cutoff, stay the same regardless of version numbers.
Provider | Current model | Reliable knowledge cutoff | What is known about the data |
|---|
OpenAI | GPT-6 Astra (predecessor GPT-5.6: February 2026) | April 2026 | Public web, licensed data, user data depending on settings |
Anthropic | Claude Opus 5.5, Sonnet 5.5 | June 2026 | Public web, third-party data, user data with consent |
Google | Gemini 4 Argon (Gemini 3 Pro was shut down in March 2026) | check with the provider | Not fully disclosed |
xAI | Grok 4.7 | May 2026 | Not fully disclosed |
Meta | Llama 4 | August 2024 | Web plus public Facebook and Instagram posts |
Perplexity | uses various base models | depends on the base model | Live search with citations partly makes up for the cutoff |
For fitness questions this means: a model with a 2026 cutoff knows studies from 2025, Llama 4 with an August 2024 cutoff doesn't. In fast-moving fields like sports nutrition, that makes a difference. My guess: models trained heavily on social media posts are more likely to pick up trend topics and myths that spread quickly there. I haven't tested that.
Rule of thumb: For the fundamentals of training planning, the current flagship models from the major providers are enough. How the models stack up on real fitness questions in a head-to-head test is shown in my AI fitness benchmark. For time-critical questions on new research, for example on supplements or sports nutrition: Perplexity or a model with web search. If you want to use Claude in a structured way, you will find a ready-made starting point in the Claude Training & Fitness Skill, and for Gemini there is the Gemini Fitness Coach as a Gem.
Gaps in the data: who is missing
Sport-science studies have a standard problem: from what I see in the literature, they mainly test young men, often sports students. Women, people over 50, beginners and people with pre-existing conditions are underrepresented.
For an LLM this means: recommendations on strength training for women in menopause rest on a much narrower foundation than recommendations for young men. The problem comes from sport science and is mirrored in the LLM. The model has read what was published, and what was published is mainly research on one particular group.
My reading for practice: if you are a 54-year-old woman who has been training for 8 months and you write a prompt without that context, you will probably end up with the recommendation for the default user, meaning the 28-year-old man with 2 years of training experience. There is no bad intent behind that, it is simply how the data is distributed.
That doesn't mean an LLM is useless for these groups. But you need to give more context when prompting and judge the answers more critically. That includes asking directly about the limits: "Which parts of this recommendation might fit my situation less well?"
Gaps by sport and the knowledge cutoff
Marathon running and cycling are well documented on the German- and English-language web, and so are powerlifting and Olympic weightlifting. For climbing, martial arts or rowing the data gets thinner, and for true niche disciplines an LLM's knowledge is often patchy.
That is simply because less text exists about them. An LLM can only learn from what was published, and niche sports have a smaller community writing about them.
Mind the knowledge cutoff
Every LLM has a fixed knowledge cutoff. Whatever happened afterwards is missing, no matter how confident the answer sounds. Which date that is for your model changes with every new version. Better not to ask the model itself, because models often get their own cutoff wrong. The provider's information is more reliable.
New training methods have a particularly hard time. A method needs time before enough is written about it online, and then more time before it makes it into a model's training data. What was published in the last few months before the cutoff, most models barely know or don't know at all.
The same goes for approaches that spread quickly in the community. Something that went viral but was barely published before may be missing from an LLM's knowledge or represented wrongly, even if everyone in your training group knows it.
How to use this when prompting
If you know where an LLM's knowledge comes from, you can ask more precisely and you know when to be sceptical.
You can only ask an AI the right questions if you can judge the answers.
The more you know about training, the better you can make up for the LLM's weaknesses. You notice when an answer is too generic. You know which recommendations have to fit your situation. And you can point the LLM to missing information or give it your own sources.
If you belong to a group that is underrepresented in the data, say so explicitly in the prompt. Age, sex, training experience, goal: this context makes the difference. Without it, you are more likely to get the standard recommendation for the default user.
The same applies to the knowledge cutoff. If your topic involves newer developments, say so directly in the prompt, for example like this:
Prompt
Your knowledge only goes up to a certain date. If you don't know newer developments on this topic, say so explicitly. I will then continue with a primary source. Also keep in mind that sport-science studies have a known bias towards young, male test subjects. My profile: [age, sex, training experience, goal, sport].
If you do a niche sport or work with a newer method, give the LLM the key basics: excerpts from studies or a short explanation of the approach. That fills the knowledge gap for this conversation. The model won't learn from it permanently, but it can work with it in this conversation.
The most direct way around the knowledge cutoff is web search. If the model can pull in current content, that at least partly makes up for the frozen knowledge. How well that works depends on the tool and on whether the search actually runs.
Tool | Web search | Activation | Note |
|---|
Perplexity | Yes, core feature | Always on | Web search is the main product, no switching required |
Gemini | Yes, via Google | Automatic | Direct Google Search integration, on by default |
ChatGPT | Yes | Automatic (Free & Plus) | Used independently on relevant prompts |
Claude | Yes | Automatic in the current app | Searches on its own in the current interface, via a toggle in older interfaces |
Last checked October 2026, subject to change
Providers keep adjusting features like web search. What runs automatically today may move behind a toggle tomorrow, or the other way round. The table shows the state of the last check in October 2026. If in doubt, check the provider's help pages.
Web search solves the cutoff problem but immediately creates a new one. The model searches the same web I described above as problematic: blogs without expertise, copy cascades, myths that rank well. If ChatGPT with web search looks for "best strength training for women over 50" and the first three hits are advice sites without a sport-science background, exactly that half-knowledge ends up in your answer, freshly crawled and nicely packaged.
Bad sources in, bad answer out, web search or not.
Web search still makes sense, especially when you know what you're looking for. In my experience, naming specific sources gets you better results than letting the model search freely. You can steer that directly in the prompt:
Prompt
Search only PubMed (pubmed.ncbi.nlm.nih.gov) for peer-reviewed studies on [topic]. Give me title, year and DOI, no free web browsing.
So the choice of sources is up to you.
Having knowledge doesn't mean applying it correctly
Even if an LLM knows a study, it doesn't necessarily apply it correctly. It can name a meta-analysis with full conviction and get the author, year or key finding wrong. There is no built-in uncertainty signal. The model sounds just as confident with a correct answer as with a wrong one.
That is a topic in its own right that goes beyond the question of sources. Where exactly this happens, with concrete fitness examples and how to spot it, is shown in Where AI training plans fail.
Frequently asked questions about AI training data
Which AI model has the best fitness knowledge?
That changes quickly. As of October 2026, Anthropic's current models state a reliable knowledge cutoff of June 2026, xAI's Grok 4.7 May 2026 and OpenAI's GPT-6 Astra April 2026. Google does not publish one for Gemini 4 Argon. For questions where new studies matter, a model with web search or Perplexity helps. How the models perform on real fitness questions is shown in my AI fitness benchmark.
Can I trust an AI training plan?
For general structures such as progression logic, basic exercises and recovery planning: yes, LLMs are solid on established training principles. For specific medical situations, injury history or strongly underrepresented groups (women over 50, niche sports), always combine the plan with your own expertise or input from a real coach.
What is a knowledge cutoff and why is it relevant for fitness?
The knowledge cutoff is the date after which the model knows nothing new. For fitness that means: studies, methods or findings published after it do not exist for the model, no matter how confident the answer sounds. Depending on the model, it currently ranges from August 2024 (Llama 4) to June 2026 (Anthropic's latest models). In fast-moving fields like sports nutrition, that difference matters.
Verdict: The LLM knows what is in the text
LLM knowledge about training is not evenly distributed. It mirrors what was published, with all the priorities, biases and gaps that brings. On top of that, the model doesn't always apply existing knowledge correctly. If you understand this, you can use the tool sensibly and build a training plan with AI that fits. If you ignore it, you get standard answers for standard situations, phrased with the self-assurance of an Olympic coach.
The LLM knows what is in the text. What is in no text, it does not know. Knowing the gaps and filling them yourself is up to you.